Introduction to RNA Sequencing


RNA sequencing (RNA-seq) revolutionizes the understanding of cellular functions, which provides researchers with an unprecedented insight into the transcriptional landscape of cells. Employing the high-throughput and accurate next-generation sequencing (NGS) technique, RNA-seq reveals gene expression profiles and describes the continuous variations in the transcriptome. In the RNA-seq technique, the single-stranded messenger RNAs (mRNAs) are selectively captured or enriched and converted to complementary DNA (cDNA) for library preparation.
At Novogene, cDNA libraries are sequenced using the state-of-the-art Illumina NovaSeq platforms, which utilizes a paired-end 150 bp sequencing strategy (short-reads) and can be applied to a wide array of research objectives. In addition to eukaryotic mRNA sequencing (mRNA-seq), we can deliver data on prokaryotic transcripts, non-coding RNAs, full-length isoforms (long-reads), whole transcriptomes and meta-transcriptomes.
Applications of mRNA Sequencing
mRNA-seq is a powerful tool to analyze the cell transcriptome profile. Novogene’s professional services help on research goals in a wide range of applications, including:
- Gene expression analysis: Quantitative profiling of transcripts across tissues, conditions and treatments to study developmental mechanisms and gene expression dynamics.
- Biomarker discovery: Identification of novel biomarkers, including transcripts, isoforms, SNP/InDel variations, and fusion genes, for clinical and research applications.
- Drug discovery and development: Transcriptomic analysis to uncover mechanisms of drug resistance and guide therapeutic strategies.
- Alternative splicing analysis: Discovery and characterization of alternative splicing events to reveal novel regulatory mechanisms and potential therapeutic targets.
- Disease diagnosis and pathogenesis: Integration of transcriptomic and multi-omics data to investigate pathogenic mechanisms, classify clinical subtypes and improve diagnostic precision.
Benefits of Novogene mRNA Sequencing
- Novogene mRNA-seq service offers high throughput and high accuracy (with Q30 score ≥ 85%) with low initial RNA input. Novogene has extensive experience providing RNA-Seq services, having successfully completed thousands of projects to help multiple researchers publish in high impact factor journals (e.g. Cell, Science, Nature, Nature Medicine, Molecular Cancer, etc.).
- Novogene offers inclusive solutions for quantification, differential gene expression, annotation of novel transcripts, alternative splicing, discovery of fusion gene and other potential variations. Highly qualified bioinformaticians deliver publication-ready data using personalized pipelines for species either with or without a reference genome.
- Extensive Experience: Novogene has extensive experience with mRNA sequencing using both long read and short read sequencing strategies.
- High-Quality Data: We deliver high-quality sequencing data that meets leading industry standards.
- Bioinformatics Support: We provide comprehensive bioinformatics support, including quantification and standard analysis.
- Quantification includes:
- Gene expression quantification
- Differential gene expressions analysis
- Functional enrichment
- Standard analysis includes:
- All the above including,
- Structural analysis such as alternative splicing and variant detection
- Our service also offers the ability to generate ‘publication ready’ figures using your database of choice. Customized bioinformatics support is also available.
- Quantification includes:
- Short Read and Long Read Sequencing: Novogene offers you the option of carrying out mRNA-seq with short read or long read sequencing strategies. Long read sequencing strategies are particularly useful for capturing the entire coding sequence, including exons, introns and untranslated regions (UTRs). This will allow distinction between different isoforms of a gene and ensures precise annotation.
- Cost Effective Strategies: Our polyA enrichment method isolates eukaryotic mRNA, reducing the sequencing of non-coding RNA and lowering overall data and processing costs.
- Fast Turnaround Times: Our sequencing labs are located near you, in Germany and the UK, allowing for reduced shipping times. With our large sequencing capacity, automated and streamlined workflows, we ensure that you receive your data promptly without compromising on quality.
- Customer Service System (CSS): Novogene’s Customer Self Service System (CSS) is an online project management portal that streamlines project management and provides direct access to all your sequencing projects in one place. You can view your sequencing project(s), track their progress, access reports, collaborate with your team members and obtain other useful information in one place.
mRNA-seq Specifications: Sample Requirements
| Service | Sample Type | Amount (Qubit®) | Volume | Concentration | RIN (Agilent 2100) | Purity (NanoDrop™) |
| Eukaryotic mRNA (polyA enrichment) |
Total RNA (animal) | ≥100 ng | ≥10 μL | ≥10 ng/μL | ≥4.0, with flat baseline | OD260/280≥2.0; OD260/230≥2.0; no degradation, no contamination |
|
Total RNA (plant, fungus) |
≥100 ng | ≥10 μL | ≥10 ng/μL | ≥4.0, with flat baseline | ||
| Total RNA (blood) | ≥400 ng | ≥20 μL | ≥20 ng/μL | ≥5.0, with flat baseline | ||
| Double stranded cDNA | ≥100 ng | ≥10 μL | ≥10 ng/μL |
Fragments between 400 bp-5000 bp, main peak at ~2000 bp |
||
| Strand-specific Eukaryotic mRNA (polyA enrichment) | Total RNA (animal) | ≥400 ng | ≥20 μL | ≥20 ng/μL | ≥5.0, with flat baseline | |
| Total RNA (plant, fungus) | ≥400 ng | ≥20 μL | ≥20 ng/μL | ≥5.0, with flat baseline | ||
| Total RNA (blood) | ≥400 ng | ≥20 μL | ≥20 ng/μL | ≥5.0, with flat baseline |
Note: Sample amounts are listed for reference only. Download the Service Specifications or Sample Requirements to learn more. For detailed information, please contact us with your customized requests.
mRNA-seq Specifications: Sequencing and Analysis
| Sequencing Platform | Illumina NovaSeq X Plus Sequencing System |
| Read Length | Paired-end 150 bp |
| Data Output |
|
| Data Analysis Capability |
|
Note: Recommended data outputs and analysis contents displayed are for reference only. Download the Service Specifications to learn more. For detailed information, please contact us with your customized requests.
Project Workflow of Novogene mRNA-seq Services
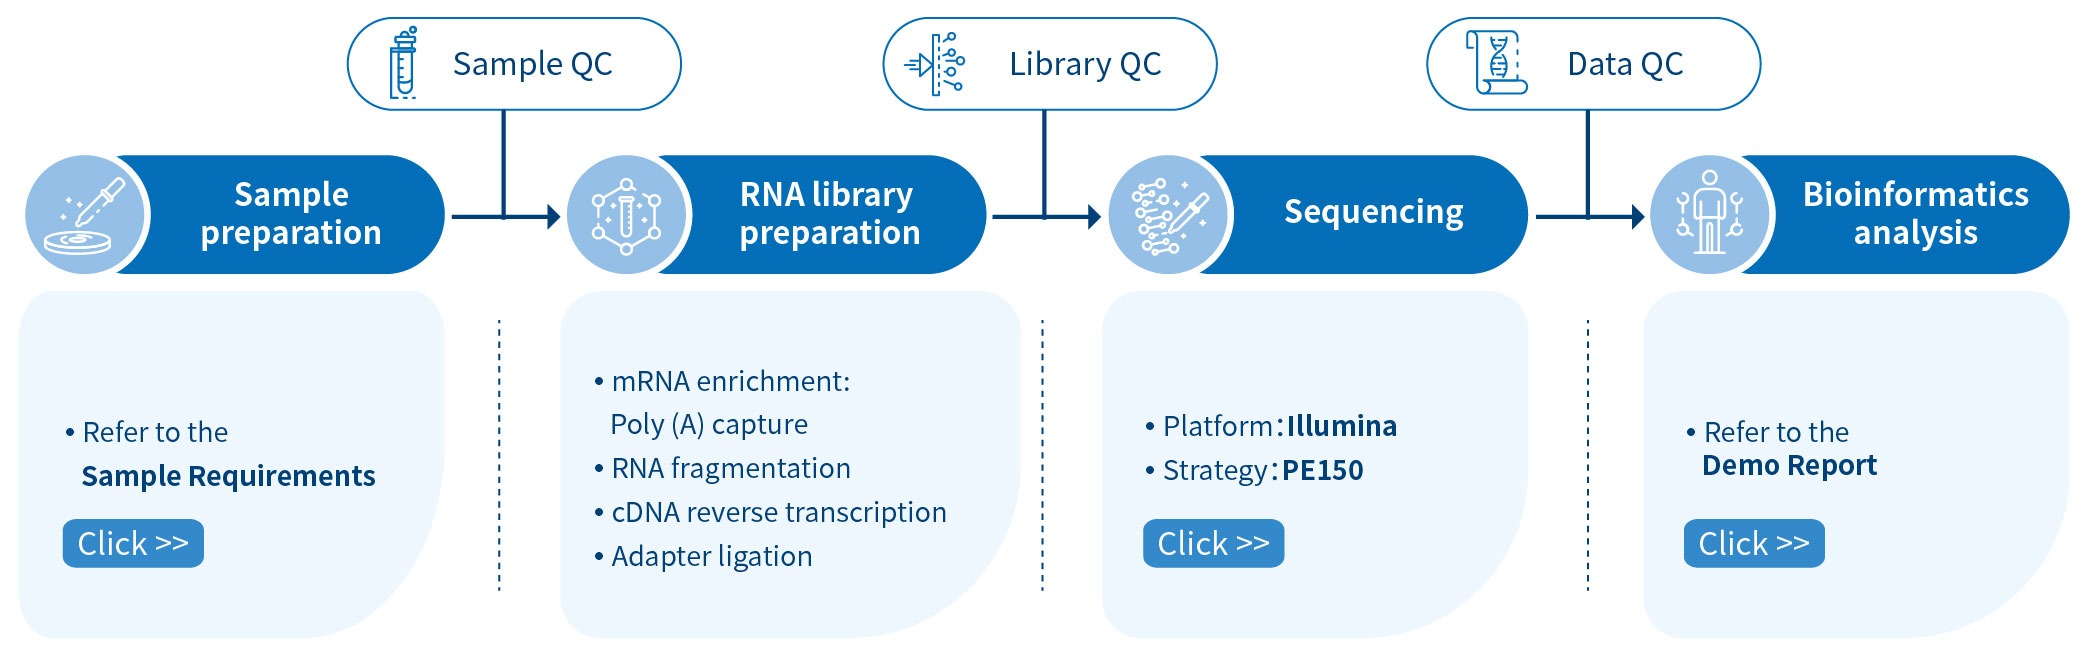
Our mRNA-Seq workflow ensures high-quality results through a rigorous, step-by-step process:
- Sample Quality Control (Sample QC): Verify that samples meet RNA-Seq requirements.
- Library preparation and Quality Control (Library QC): Create RNA libraries through polyA capture and reverse transcription into cDNA, followed by quality assessment.
- Sequencing: Perform 150 bp paired-end sequencing using Illumina PE150 technology.
- Data Quality Control (Data QC): Assess sequencing data for quality and reliability.
- Bioinformatics Analysis: Deliver comprehensive, publication-ready results.
The accompanying flowchart illustrates each stage of the mRNA-Seq service.
Featured Publications using Novogene’s RNA-seq service
RNA-seq (mRNA-seq) is the most frequently cited NGS method. Here we have summarized some outstanding academic publications that used Novogene RNA sequencing (mRNA Sequencing) services.
-
Protein ScienceIssue Date: 21 February 2025IF: 4.5DOI: 10.1002/pro.70072
-
NATURE MEDICINEIssue Date: 25 September 2023IF: 82.9DOI: 10.1038/s41591-023-02553-8
-
Macrophage fumarate hydratase restrains mtRNA-mediated interferon production
NATUREIssue Date: 8 March 2023IF: 69.504DOI: 10.1038/s41586-023-05720-6
-
B cells orchestrate tolerance to the neuromyelitis optica autoantigen AQP4
NATUREIssue Date: 21 February 2024IF: 64.8DOI: 10.1038/s41586-024-07079-8
-
In vitro production of cat-restricted Toxoplasma pre-sexual stages
NATUREIssue Date: 13 December 2023IF: 64.8DOI: 10.1038/s41586-023-06821-y
-
Defective pollen tube tip growth induces neo-polyploid infertility
SCIENCEIssue Date: 1 March 2024IF: 56.9DOI: 10.1126/science.adh0755
-
TREX reveals proteins that bind to specific RNA regions in living cells
NATURE METHODSIssue Date: 19 February 2024IF: 48DOI: 10.1038/s41592-024-02181-1
-
Cell Death & DifferentiationIssue Date: 2021.2IF: 10.717DOI: 10.1038/s41418-021-00749-4
-
Stem Cells Translational MedicineIssue Date: 2021.1IF: 11.5DOI: 10.1002/sctm.20-0468
-
Journal of Hazardous MaterialsIssue Date: 2020.12IF: 9.038DOI: 10.1016/j.jhazmat.2020.124867
-
Genome MedicineIssue Date: 2020.11IF: 10.675DOI: 10.1186/s13073-020-00796-5
-
Advanced scienceIssue Date: 2020.3IF: 15.84DOI: 10.1002/advs.202000398
Error Rate Distribution

The x-axis shows the base position along each sequencing read and the y-axis shows the base error rate.
GC Content Distribution

The x-axis for reads position, the y-axis for single base percentage. Different color for different base type.
Classification of Raw Reads

Reads Distribution on Reference Genome

Gene Expression Quantification

The x-axis represents the name of sample, the y-axis indicates the log10(FPKM+1), parameters of box plots are indicated, including maximum, upper quartile, mid-value, lower quartile and minimum.
Volcano Plot of changes on Gene Expression

The x-axis shows the fold change of genes in different samples. The y-axis shows the statistically significant degree of changes in gene expression levels. The smaller the corrected pvalue, the bigger -log10(corrected pvalue), the more significant the difference. The points represent genes, blue dots indicate no significant difference in gene expression, red dots indicate upregulated differentially expressed genes, green dots indicate downregulated differentially expressed genes.
Hierarchical Clustering Heatmap of Differential Expression

The overall results of FPKM cluster analysis, clustered using the log10(FPKM+1) value. Red denotes genes with high expression levels, and blue denotes genes with low expression levels. The color ranging from red to blue indicates log10(FPKM+1) value from large to small.
